What emfor does
emfor is a health-check daemon that runs on every application host. It
checks the backends of the services your applications use, and publishes
which backends are healthy in a file on the same host. An application that
needs, say, a database server asks the emfor client library for one; the
library reads the local file and returns an address such as
10.0.3.1:5432. The lookup sends nothing over the network, takes about a
microsecond, and keeps working when other hosts, or the network, fail.
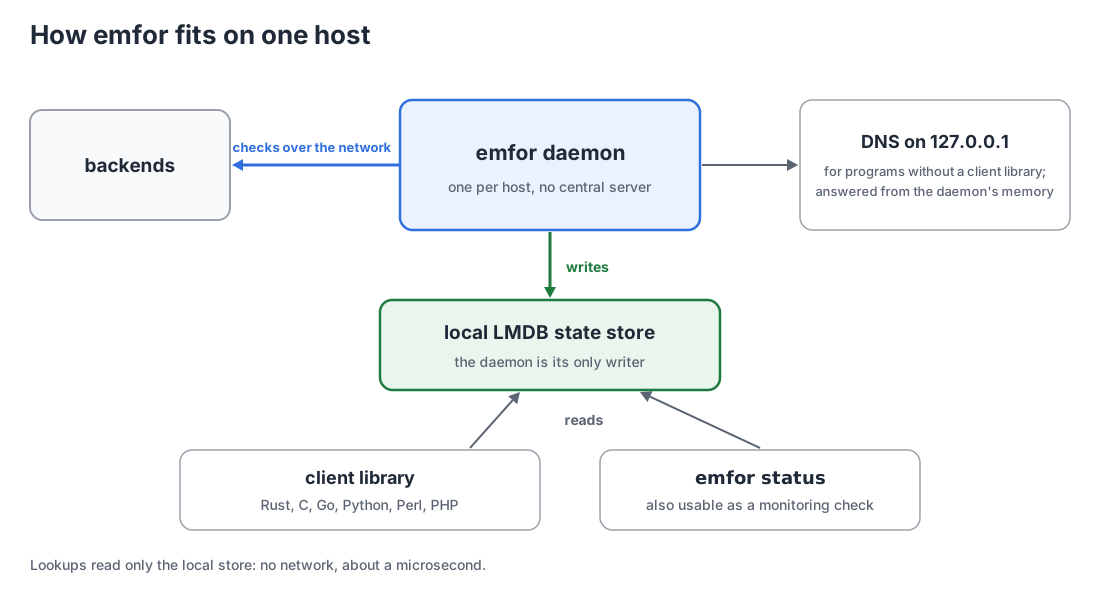
Each host runs its own daemon with its own config and sees the backends from where it stands. There is no central server. The daemons of one data centre can optionally form a peer group to pass failures on and to vote on each backend; lookups still read only the local store.
The parts
| Part | What it is |
|---|---|
emfor server | The daemon. It reads emfor.toml, checks every backend repeatedly, and writes the results to the state store. One per host (one per store). |
| The state store | An LMDB file, /var/lib/emfor/state.mdb by default, with one record per service. The daemon is its only writer; any number of processes read it. |
| Client libraries | emfor_client (Rust) and libemfor (C), with wrappers for Go, Python, Perl and PHP. A lookup reads the store and picks one backend. |
| DNS server | Optional. Answers A, AAAA and SRV queries for service names in one zone, from the daemon’s memory, for programs that cannot use a client library. |
emfor status | Shows what the daemon has published. Also usable as a monitoring check. |
/metrics | Optional Prometheus endpoint. |
emfor-check | A plugin program with checks for redis, MySQL/MariaDB, PostgreSQL, LDAP, DNS, RADIUS, SIP, Diameter, SMTP, AMQP, MongoDB, gRPC, QUIC and HTTP/3. |
Services and backends
A service is a name, such as api.svc.emfor, with a list of
backends: the ip:port addresses that serve it. Each service has a
check (how to test one backend), timing settings, a balance method
(how to choose among healthy backends) and an on_all_down policy (what
to do when none is healthy).
[services."api.svc.emfor"]
check = "http"
backends = ["10.0.0.11:8080", "10.0.0.12:8080"]
Backends are always IP addresses, never host names: emfor does not depend on DNS to find them.
Check results and health states
Every check ends with one result:
| Result | Meaning | Counts against the backend |
|---|---|---|
up | The backend passed. | No |
down | The backend failed (refused, timed out, wrong answer). | Yes |
error | emfor could not perform the check (a local problem such as an unreadable password file or a crashed plugin). | No |
Each backend has a health state:
| State | When |
|---|---|
unknown | After the daemon starts, after the backend is added, after its check changes, and after a long run of error results. |
healthy | After rise consecutive up results (default 2). |
unhealthy | After fall consecutive down results (default 3). |
The counters make a single lost packet harmless: one failed check does not
remove a backend, and one passed check does not bring it back. An error
changes nothing, so a problem on the checking host does not mark good
backends down; only when a backend has had nothing but errors for longer
than fall × interval does it go back to unknown.
What a lookup returns
The client takes the service’s healthy backends as candidates and lets
balance pick one. When none is healthy, on_all_down decides:
open(the default): the application gets a backend anyway, which is usually better than failing outright when the checks, not the backends, are at fault. Backends stillunknown(not yet decided, or whose checks only give errors) come before those known to beunhealthy; see chapter 5.closed: the lookup fails withALL_DOWN, and DNS answersSERVFAIL.
The heartbeat and a stale store
The daemon writes a heartbeat (the current time) into the store at
least once a second. A client compares it with its own clock: when the
heartbeat is more than 3 seconds old (EMFOR_MAX_STALENESS), or the
daemon has stopped and set it to 0, the store is stale. In a stale
store the client treats every backend as not healthy, and on_all_down
decides. An application therefore never trusts health data from a daemon
that has hung or gone away, and it still gets an address from an open
service.
When the daemon starts it rewrites every service record with all backends
unknown; it never reuses health state from a previous run. While a
backend is unknown it is checked about every 200 ms, so with the default
settings every backend is known within about half a second of a start.
Peer groups
Hosts in one data centre see the same backends. Without help, each daemon
needs fall failed checks of its own to notice that a backend went down.
In a peer group, the daemons of one site that list each other under
[peers] (chapter 3) send each other
authenticated UDP messages:
- a heartbeat every second, so each member knows which others are live;
- when a member sees a backend go from
healthytounhealthy, a report to every other member, which then rechecks that backend at once and every 200 ms, up tofallchecks, instead of waiting for its nextinterval.
A report never changes a backend’s state by itself. What does is the
majority vote: with at least three live members (this one included),
every backend has three assigned checkers, chosen from the live members
by hashing the service, the backend and each member’s address, so members
that see the same live members pick the same three. For a few seconds after
a member starts, stops or becomes unreachable, members may disagree on who
is live and so on the three. After each of its own checks an assigned
checker sends its result (up or down) to the others. After each of its
own checks, every member counts the results of that backend’s assigned
checkers that are recent (from the last three of the sender’s intervals)
and come from a member with the same check definition:
- two or more
downvotes: the backend counts as down here too, even if this host’s own check passed; the reason readspeers 2/3: <reason>(down votes / votes counted); - otherwise this host’s own result counts, and a
downreadslocal: <reason>: this host sees a problem the others do not; - with fewer than three live members, or no vote at all, the own result counts unchanged, as without a group.
The counted result then goes through rise and fall as usual. Each
result a member sends counts at one check time only: a member with a short
interval does not count a slower member’s single down again and again,
and a check that only repeats votes already counted (with the own check
passing) changes nothing. A backend
that the group sees down while this host’s own check passes is shown by
emfor status with the marker local-up. Lookups still read only the
local store. Members that are not reachable change nothing: the vote falls
back to each daemon’s own checks. There is no master, and a group never
spans two sites. A service can be left out of the group with
peers = false (chapter 3); the host tells
the other members, which then choose the service’s assigned checkers
among the rest.
The checks are split, too. A member that is not an assigned checker of a
backend does not check it while two of its assigned checkers agree: two
up votes count as up, two down votes as down (peers 2/3:). It
still makes its own check, with the service’s usual check, at least
every third interval, and every time while there are fewer than two
agreeing votes. When its own check fails while the assigned checkers see
the backend up, it starts a fast recheck run (every 200 ms, up to fall
checks, as after a peer’s report) and then checks every interval until
its own check passes, so a failure only this host sees still reads
local: <reason>; such a failure is noticed within about three
intervals plus fall fast checks instead of fall checks. With three
assigned checkers and N members a backend gets about 3 + (N − 3) / 3
checks per interval instead of N.
Failure behavior at a glance
| What fails | What applications see |
|---|---|
| One backend | It turns unhealthy after fall failed checks (about 6 seconds with the defaults) and is no longer returned. In a peer group, once one member has noticed, the others follow within about a second; when two of its three assigned checkers see it down, every member marks it down after fall checks, also where it still answers. A failure that only one member that is not an assigned checker sees takes up to about three intervals longer there, but then needs fall checks 200 ms apart instead of fall intervals (with the defaults it is down there after at most about 6.4 seconds, against 6 without a group). |
| Every backend of a service | open: an unknown backend if there is one, otherwise any backend; closed: ALL_DOWN / SERVFAIL. |
| The emfor daemon stops or hangs | After 3 seconds the store is stale: open services return any backend, closed services fail. Lookups never block. |
| The store file is missing or unreadable | Lookups fail with UNAVAILABLE. |
| The checking host loses its network | Checks fail, backends turn unhealthy; the applications on that host cannot reach them either. |
| A plugin crashes or stops answering | Its checks are error (no state change) until the daemon has restarted it. A plugin that leaves 3 requests in a row unanswered is killed and restarted. |
Files the daemon uses
| File | Purpose |
|---|---|
/etc/emfor/emfor.toml | The config. Another path with --config. |
<store> (/var/lib/emfor/state.mdb) | The state store. |
<store>-lock | LMDB’s lock file. Every reader registers in it, so applications need write access to it. |
<store>.writer | Held locked by the running daemon, so that only one daemon writes a store. |
<store>.corrupt | A damaged store moved aside at start, kept for inspection. |